Qwen Models: The Cheapest Input Rate on the Site Is Not the Cheapest Row to Run
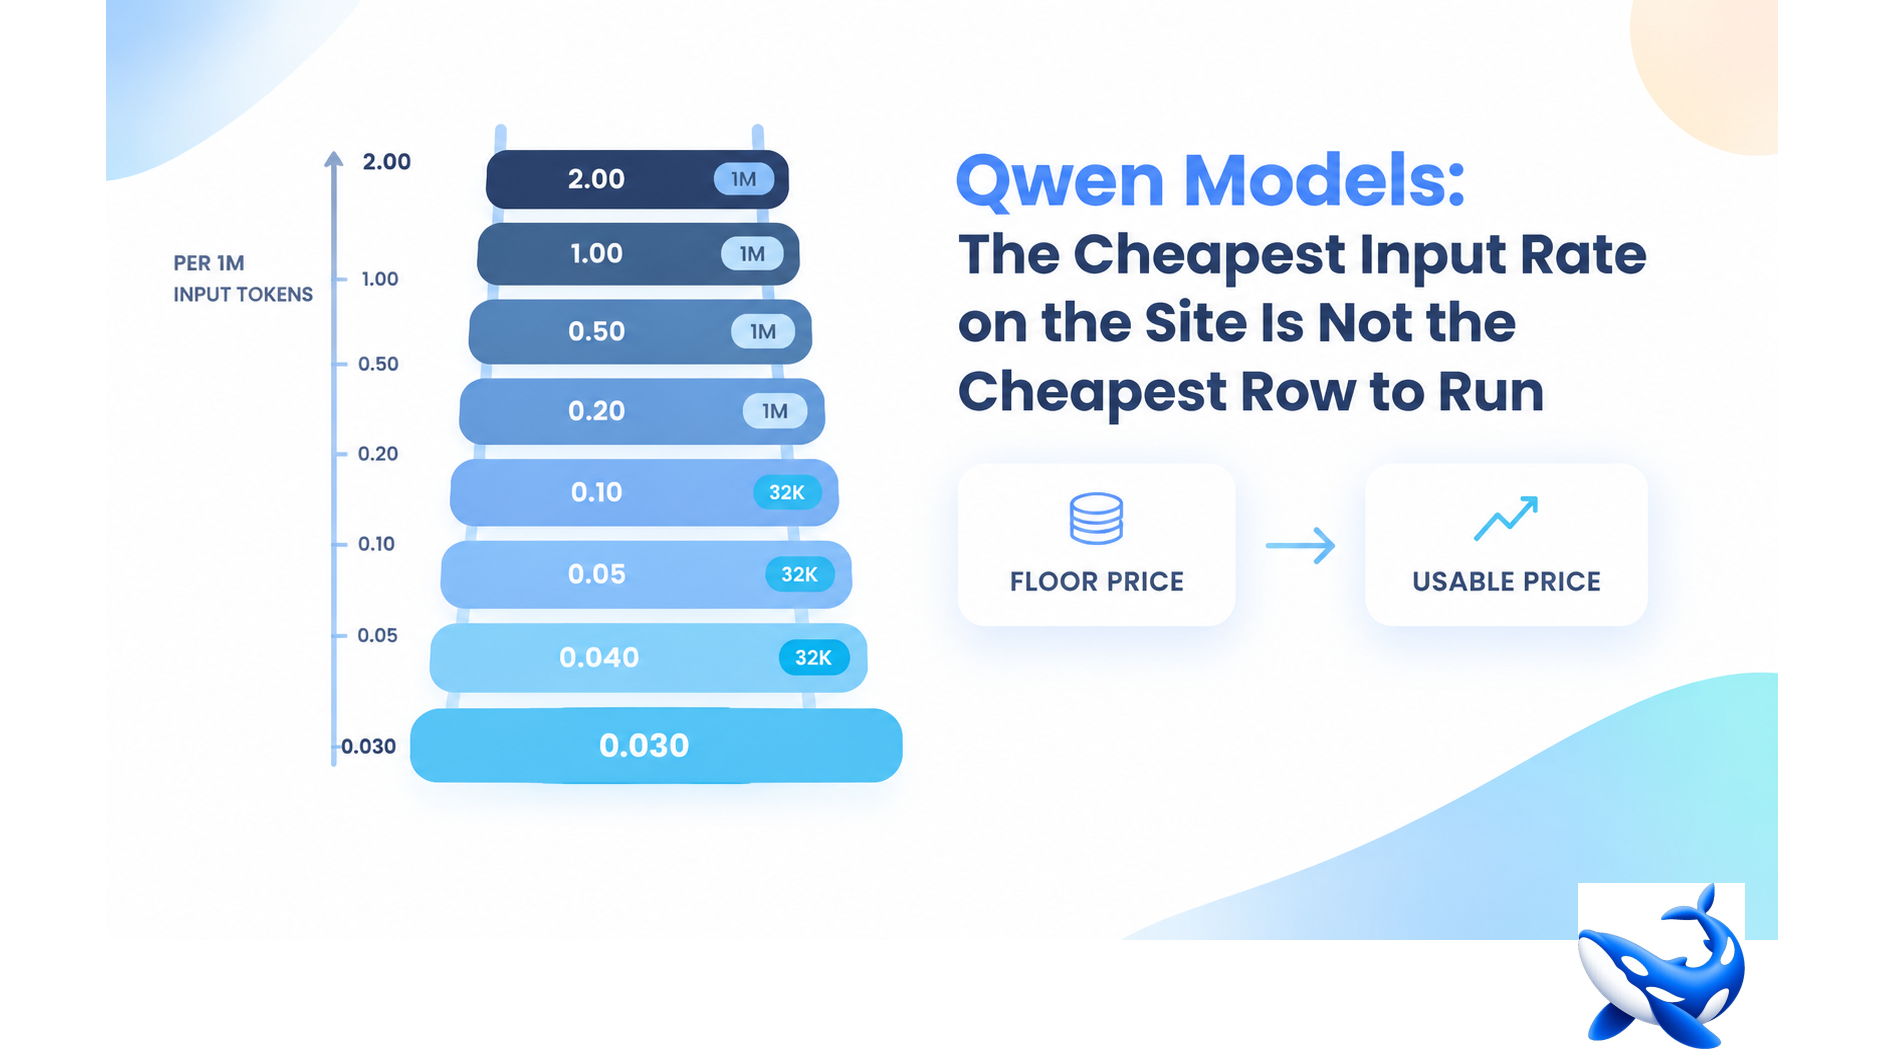
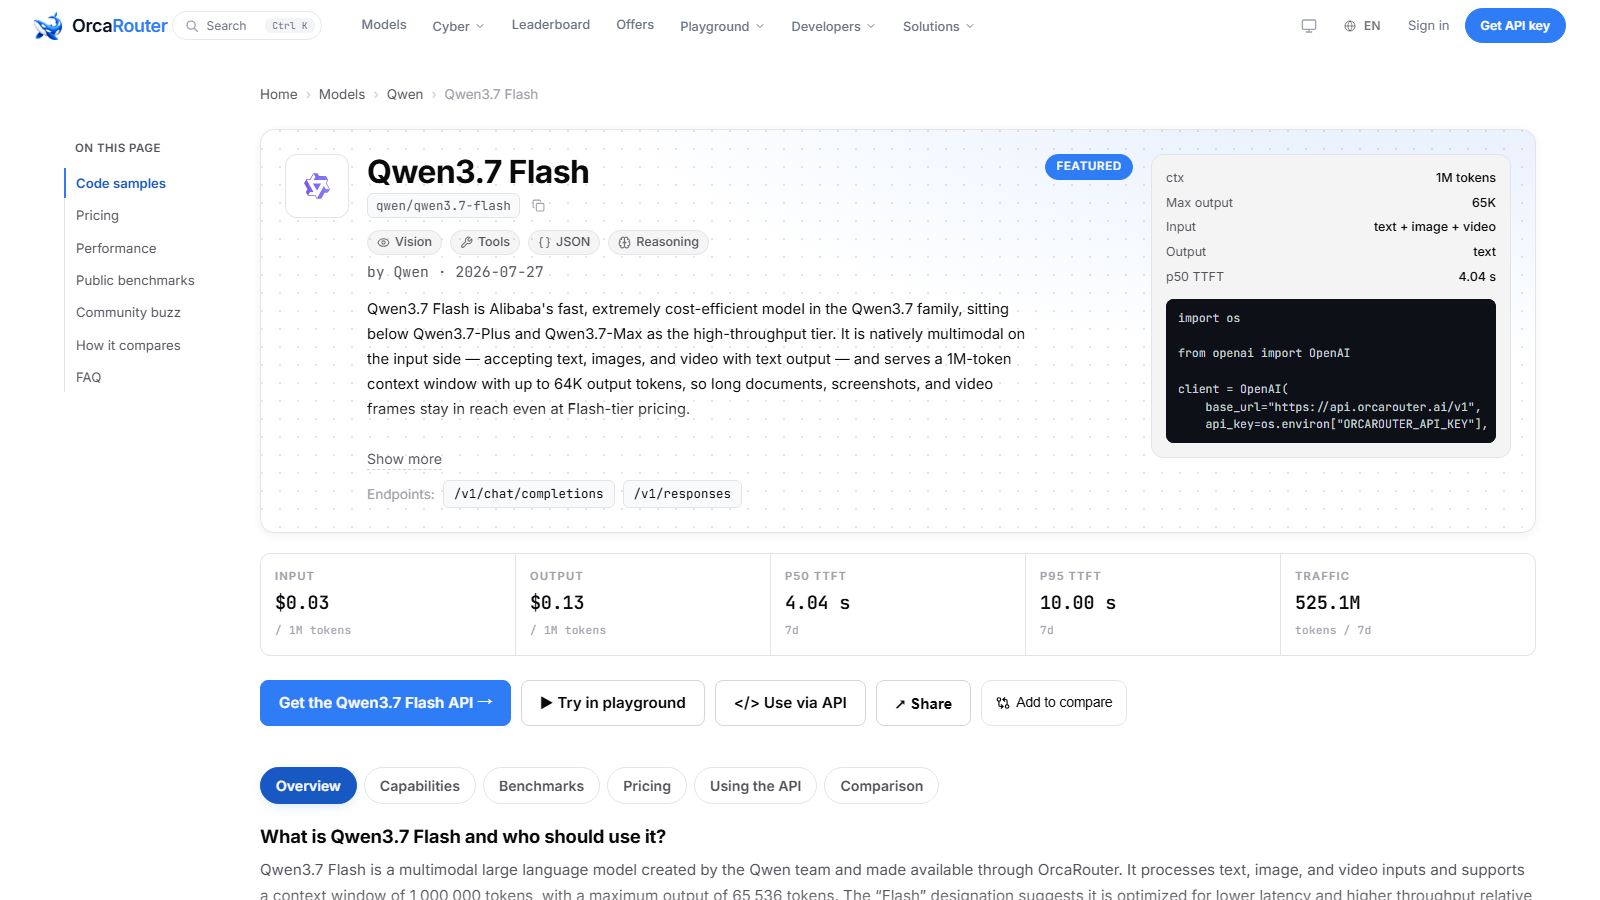
The lowest input rate on any generation model on this site is $0.030 per million tokens, charged by Qwen3.7 Flash on the OrcaRouter Qwen models page — 67 times below the $2.00 per million the same table charges for Qwen3.8 Max. That is what a sorted price column hands you if you read the top line and stop. The qualification arrives in the column beside it: the cheapest rung is a single configuration, and the rungs just above it are narrower than they look.
A rate card invites exactly one reading mistake. You sort by input price, take the bottom row, and treat the number as the catalogue’s price. On most tables that is roughly harmless. On this one it is not, because the cheap end of the column and the usable end of the column are not the same end — four of the seven cheapest input rates here sit on a 32K window, and no amount of cheap input makes a 32K row do a 1M job.
The arithmetic under the superlative
Read the ratio before the rate. Qwen3.8 Max is listed at $2.00 per million input and $6.00 per million output; Qwen3.7 Flash is listed at $0.030 and $0.130. Input spreads 67-fold across that pair, output spreads 46-fold, and the blended figure — the average of the two rates — spreads 50-fold, from $0.080 to $4.00 per million.
Put a volume on it. A workload that reads 12 million tokens and writes 3 million tokens a month costs $0.75 on the cheap row: 12 × $0.030 is $0.360 for the reads and 3 × $0.130 is $0.390 for the writes. The same workload on the dearest row costs $42.00 — 12 × $2.00 plus 3 × $6.00. That is 56 times the bill for the same token count, and nothing in those two numbers tells you which row deserves the markup. Prices here are the provider’s published rates with $0 markup added, so the gap is Qwen’s pricing decision, not a gateway margin.
One row on the site undercuts $0.030, and it is worth naming because it is the comparison people reach for first. On the OpenAI provider page the cheapest input rate anywhere is $0.02 per million tokens, on openai/text-embedding-3-small — an embedding model, which cannot answer a prompt. So the cheapest generation rate on the site and the cheapest rate of any kind on the site are not the same row, and the row that wins the second comparison is not a row you can chat with.
The page disagrees with its own header
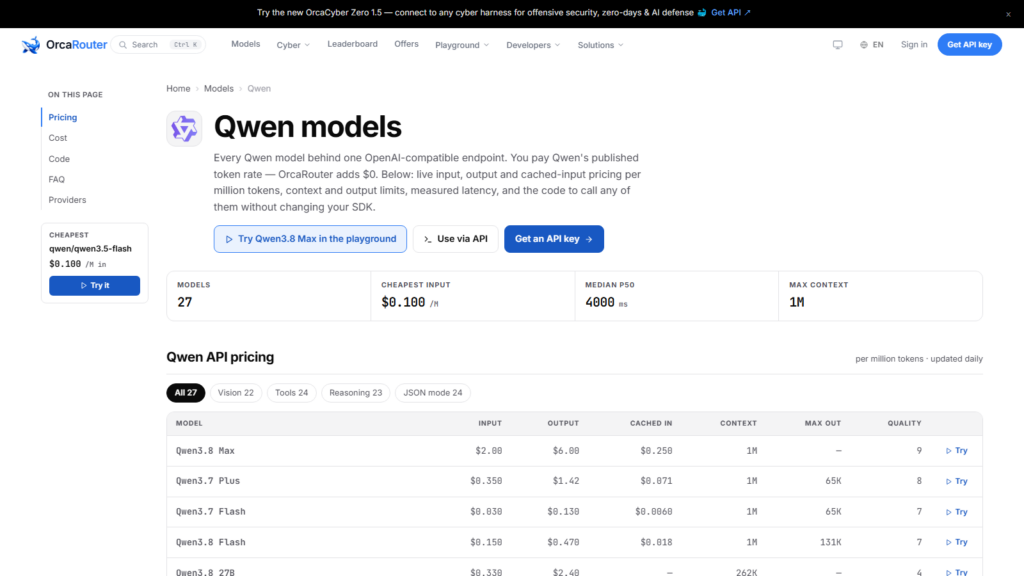
There is a second reason to distrust the single number, and it is on the page itself. The header statistic on the Qwen page prints a cheapest input of $0.100 per million tokens. The pricing table below it prints a $0.030 row. The FAQ agrees with the header and not with the table: it names qwen/qwen3.5-flash as the cheapest Qwen model at $0.1 per million input — which is that row’s own rate, and not the lowest rate in the column above it.
Three surfaces, two answers. We are not going to resolve which one the page means, because the page does not; what a reader should take from the disagreement is that the headline statistic is not a substitute for sorting the column. Sort it, and $0.030 is where the column lands
 .
Four of the seven cheapest rows stop at 32K
This is where the floor price stops being the price you pay. Sorting the input column from the bottom gives $0.030, $0.057, $0.086, $0.100, $0.115, $0.150, $0.172. Four of those seven carry a 32K context window:
| Row position by input price | Input / output per 1M | Context | Our 0–10 composite |
| Qwen3.7 Flash ($0.030) | $0.030 / $0.130 | 1M | 7 |
| Qwen3.5-35B-A3B ($0.057) | $0.057 / $0.459 | 32K | 6 |
| Qwen3.5-27B ($0.086) | $0.086 / $0.688 | 32K | 6 |
| qwen/qwen3.5-flash ($0.100) | $0.100 / $0.400 | 1M | 6 |
| Qwen3.5-122B-A10B ($0.115) | $0.115 / $0.917 | 32K | 7 |
| Qwen3.8 Flash ($0.150) | $0.150 / $0.47 | 1M | 7 |
| Qwen3.5 397B A17B ($0.172) | $0.172 / $1.03 | 32K | 8 |
The 0-to-10 composite in the last column is our own score — our measurement of each model across the dimensions we grade it on, not a third-party benchmark — and it carries that label every time it appears here. Read the context column instead of the price column and the ordering breaks completely: four of those seven rows sit at 32K, which is not a smaller version of a 1M window but a different class of job. A document that fits in 1M tokens does not fit in 32K, and there is no rate advantage that compensates for a row that cannot accept the request.
So the cheap end of this table is not a cheaper way to run the same work. It is a set of rows for shorter work, priced accordingly.
What the usable ladder looks like
If the job needs a 1M window and a composite of 8 or better, the ladder reorganises itself. The floor row at $0.030 gives 1M and a composite of 7 with a 65K maximum output. The first 1M row above a composite of 7 is Qwen3.6 Plus at $0.276 — 9.2 times the floor. The first 1M row at a composite of 9 is Qwen3.8 Max at $2.00, 67 times the floor, and the 0902 variant of that model carries the same $2.00 and the same 9.
Read as a ladder rather than a floor, the usable rungs run roughly $0.030, $0.100, $0.150, $0.276 and then a long climb through qwen/qwen3.5-plus at $0.400, qwen/qwen3-max-preview at $0.861, Qwen3.7 Max at $1.25 and Qwen3.8 Max at $2.00. Three observations fall out of that climb. Qwen3.7 Max is priced at $1.25 — more than four times Qwen3.6 Plus — and carries a composite of 5, below rows that cost a tenth of it, which is the clearest evidence on the page that price and our quality score move independently. qwen/qwen3.5-flash at $0.100 is cheaper than everything above it and still holds the 1M window. And the ceiling row is not the only 1M row at the top of the ladder; it is simply the one priced like a flagship.
Where the floor price is the right price
None of that argues against the cheap row. It argues for reading it with the window in hand.
If your workload is short-prompt, high-volume generation — classification passes, extraction, routing decisions, short rewrites — the 32K rows at $0.057 and $0.086 are doing exactly what their price suggests, and our composite of 6 on each of them is a tier, not a verdict. If your workload reads long documents, the floor row at $0.030 is genuinely the cheapest 1M row in the catalogue, and the question becomes whether a composite of 7 and a 65K maximum output clear your bar. If they do, you have found the cheapest long-context row on the site. If they do not, the next 1M rung is $0.276, and the honest comparison is $0.030 against $0.276 rather than $0.030 against a 32K row priced in between.
The one number to keep out of the decision is the header statistic. It reads $0.100, which is neither the floor nor the cheapest 1M row’s rate.
The takeaway
The cheapest input rate on this site is $0.030 per million tokens, and it belongs to one row with one window size, one maximum output and a composite of 7 that we build ourselves rather than import from a benchmark. The table underneath it sells four rows cheaper than $0.200 that stop at 32K, one 1M row at $0.100, and then a ladder that doubles and redoubles up to $2.00. Sorting by price and stopping at the top of the column is how you end up buying a 32K window at a name that promised a 1M one. Sort by window first, price second — the two orderings disagree, and the disagreement is the actual product decision.
Sourcing note: all model names, prices, context windows, maximum-output figures and header statistics are read from the OrcaRouter Qwen provider page and the linked model page on 2026-10-14, and are the provider’s published rates with $0 markup [VENDOR]. The header statistic and the FAQ on that page state a cheapest input of $0.100 while the pricing table prints $0.030; both are quoted as found. The embedding-row comparison comes from the OpenAI provider page, read the same day [VENDOR]. The 0-to-10 quality figures are our own composite — our measurement of each model across the dimensions we grade, not a third-party benchmark [OURS]. Prices are live and will drift. All checked 2026-10-14.